Affordance & Causality
363Why this tool, and what changes because of it?
 Citation
EGOCENTRIC INTELLIGENCE
Beyond seeing.Understand the tool.
EgoTools is a 100-hour dataset, a diagnostic benchmark, and an 8B reference model for reasoning about tools in real-world first-person video.
Cite this work BibTeX ↗Transfer without piercing
THE FULL STORY
The complete EgoTools project film—from real-world collection to tool-centric narration, grounding, evaluation, and learning.
THE DATASET
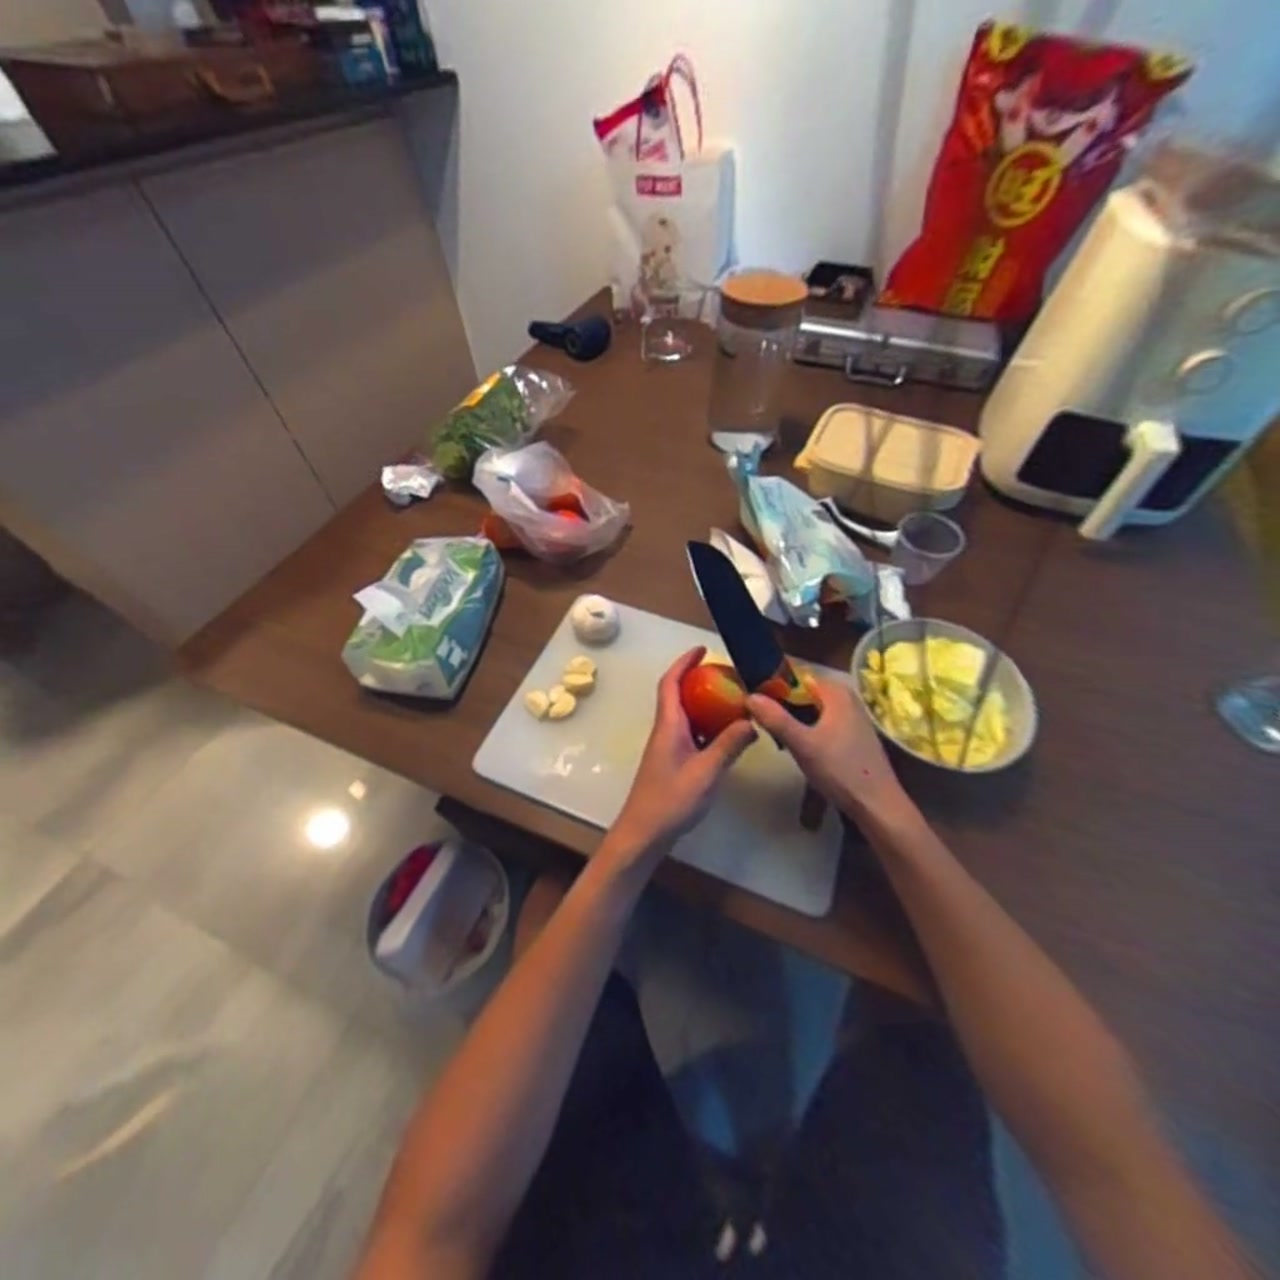
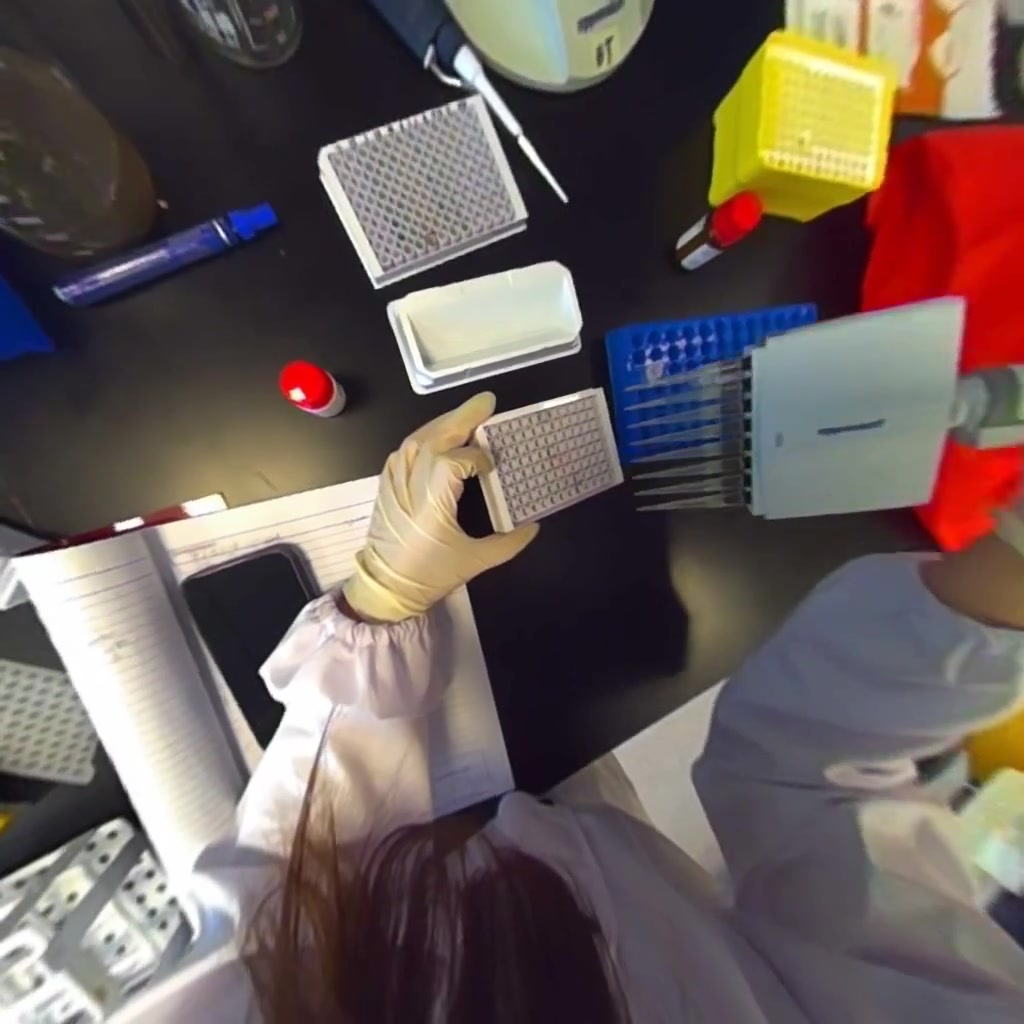
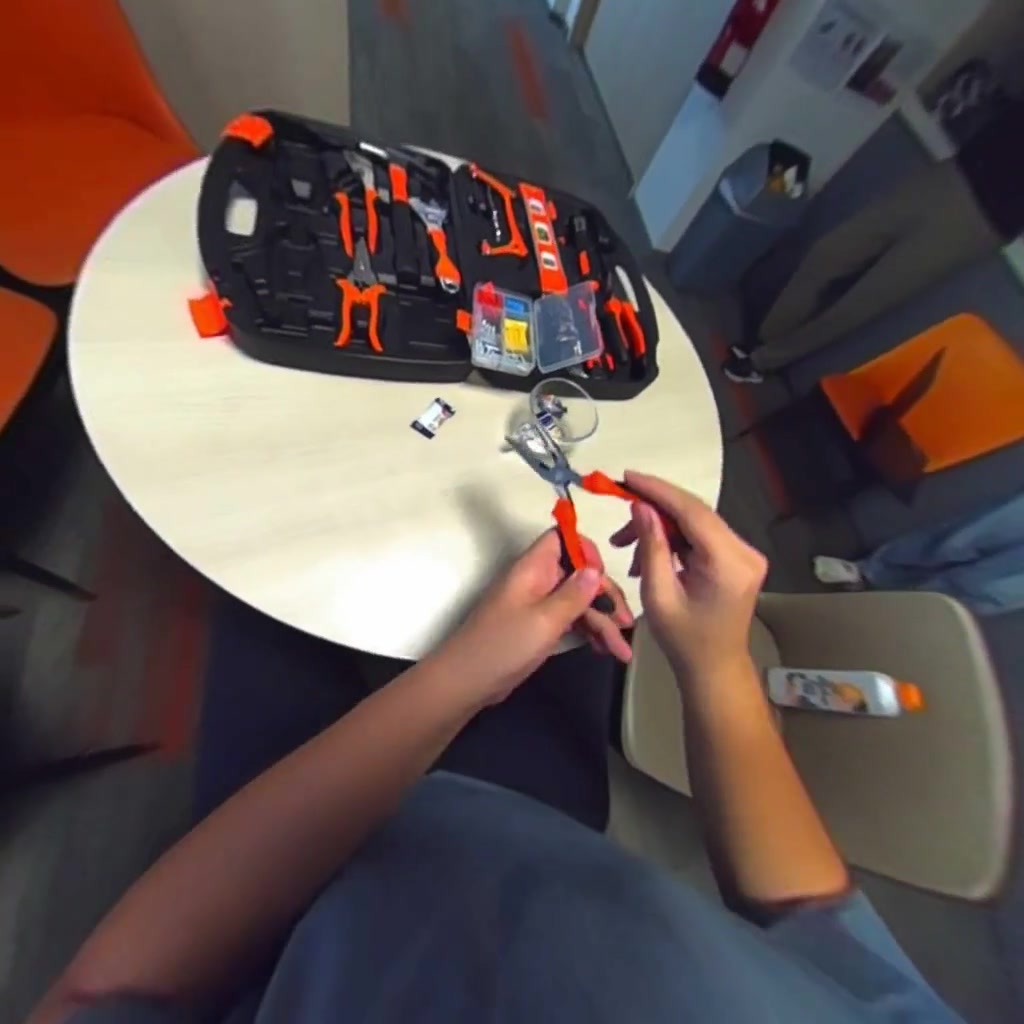
From kitchens and labs to workshops and living spaces, EgoTools captures how people choose and use tools during real tasks.
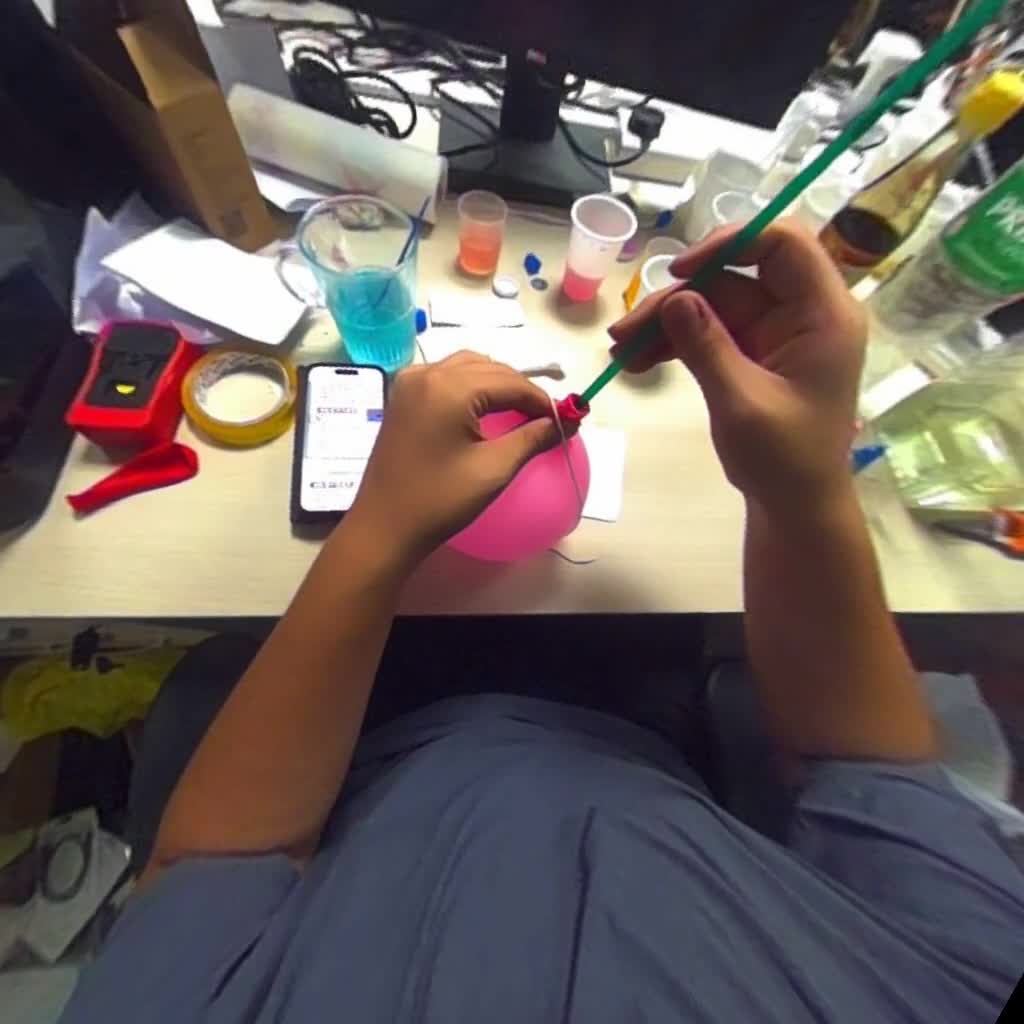
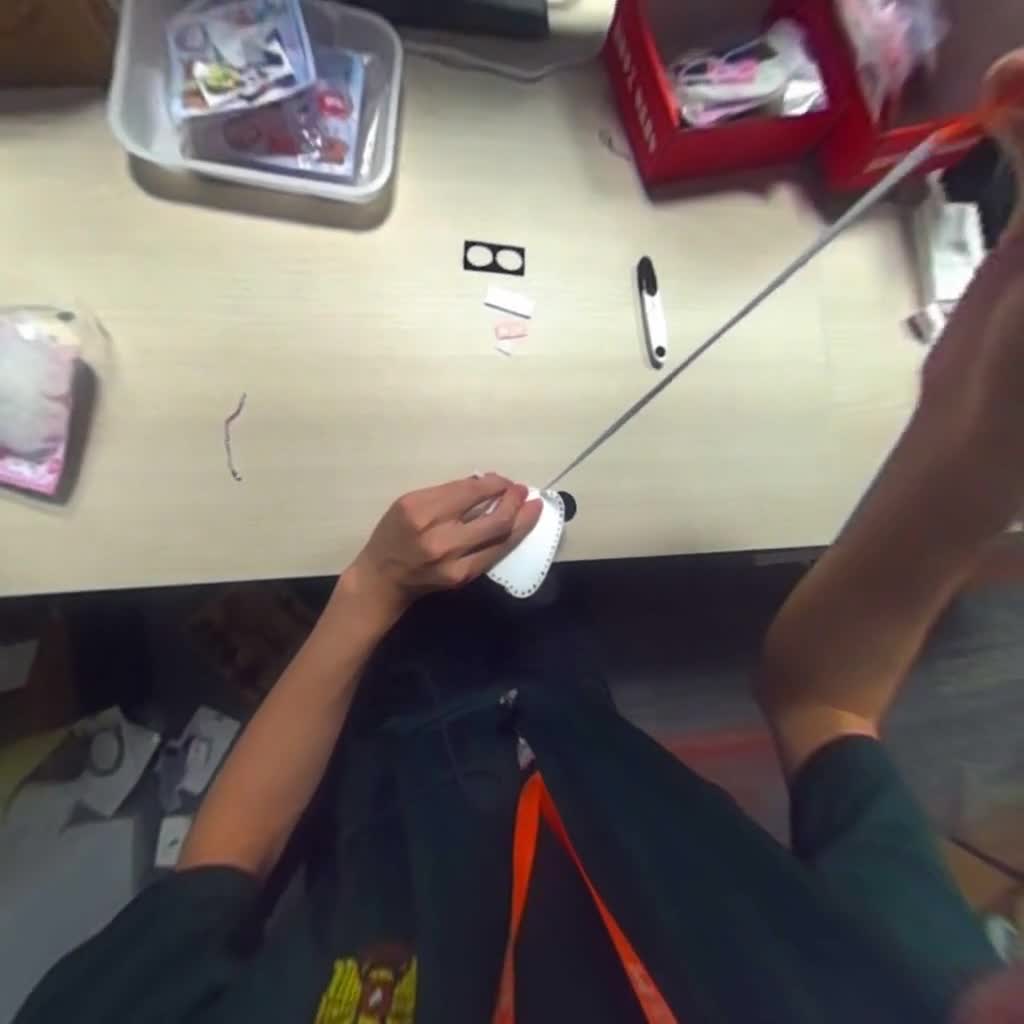
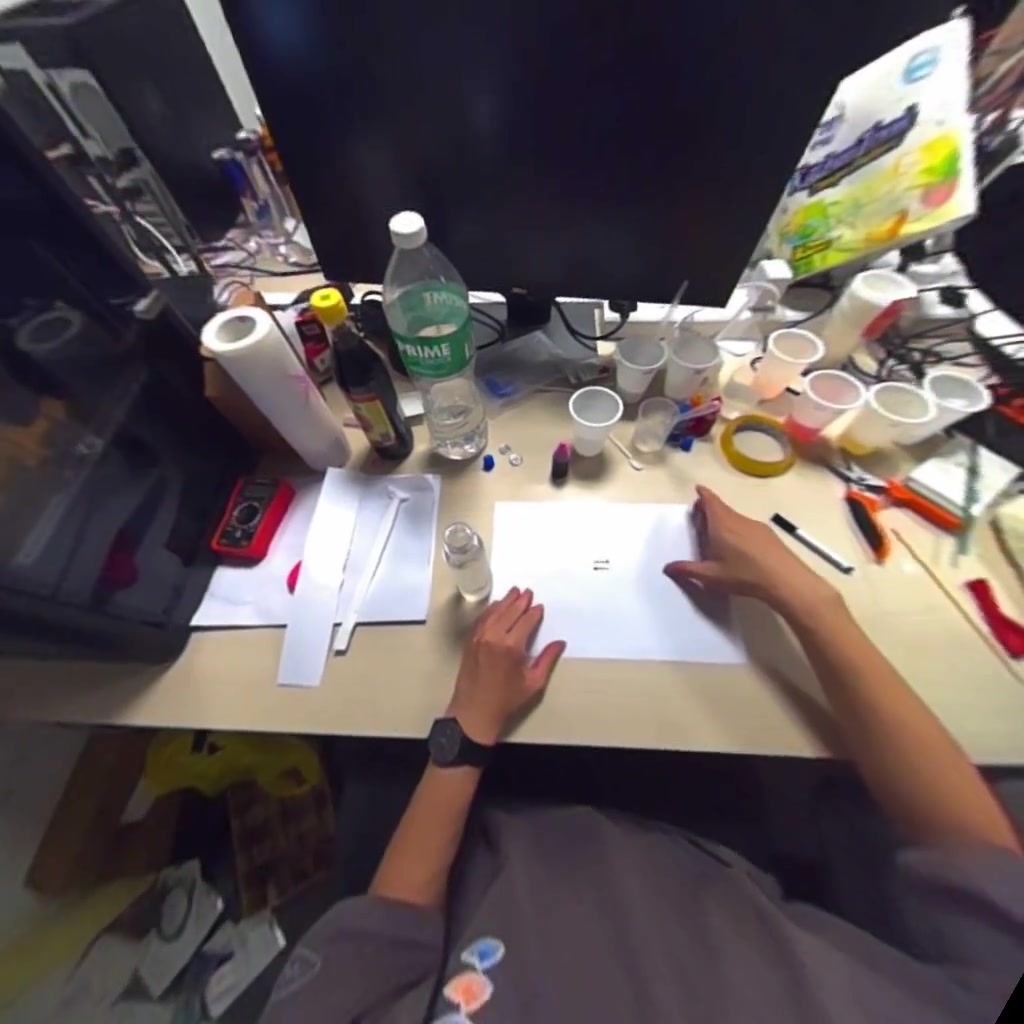
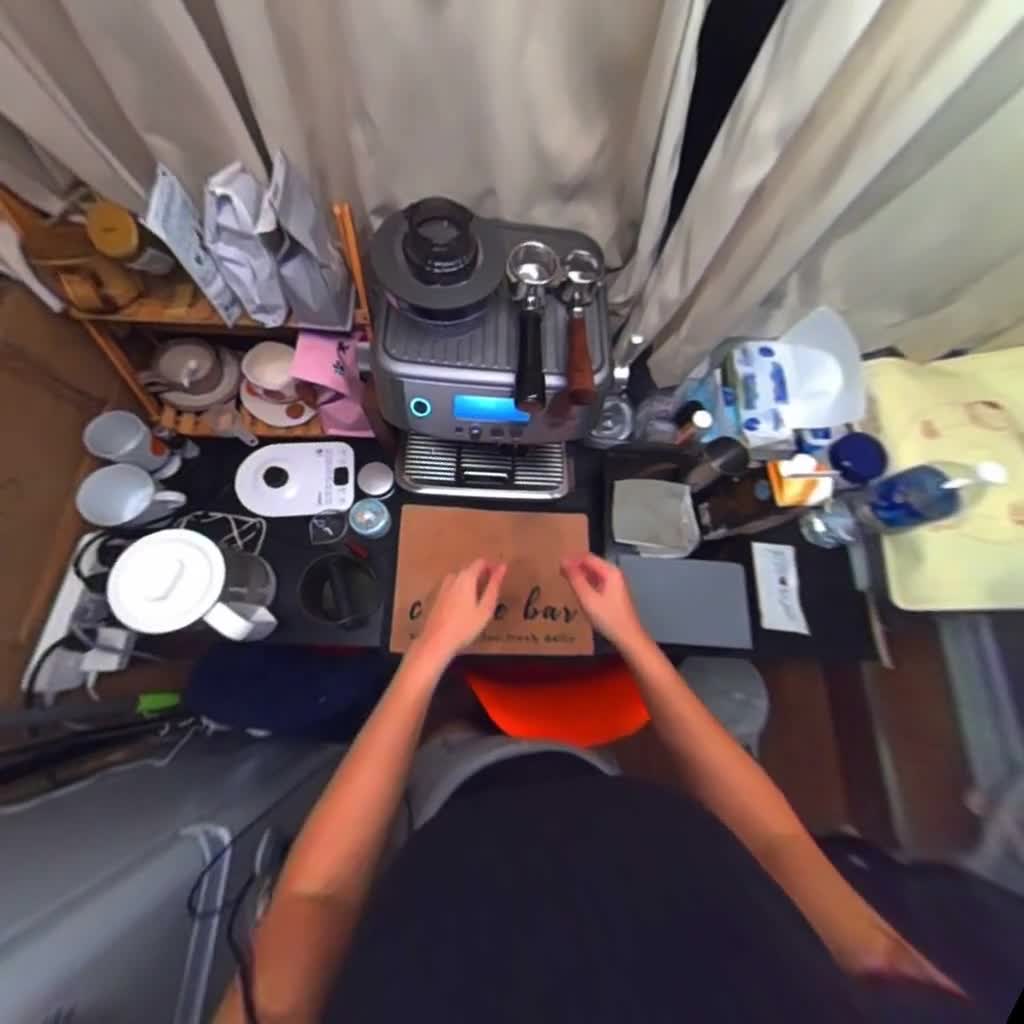
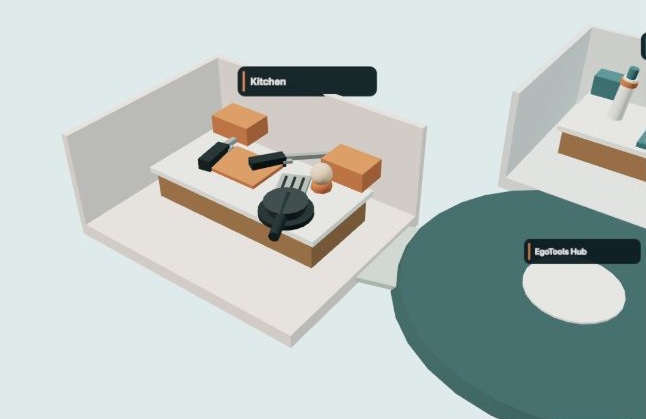 Interactive demo
Explore three rooms. Pick a tool.
Discover the video behind it.
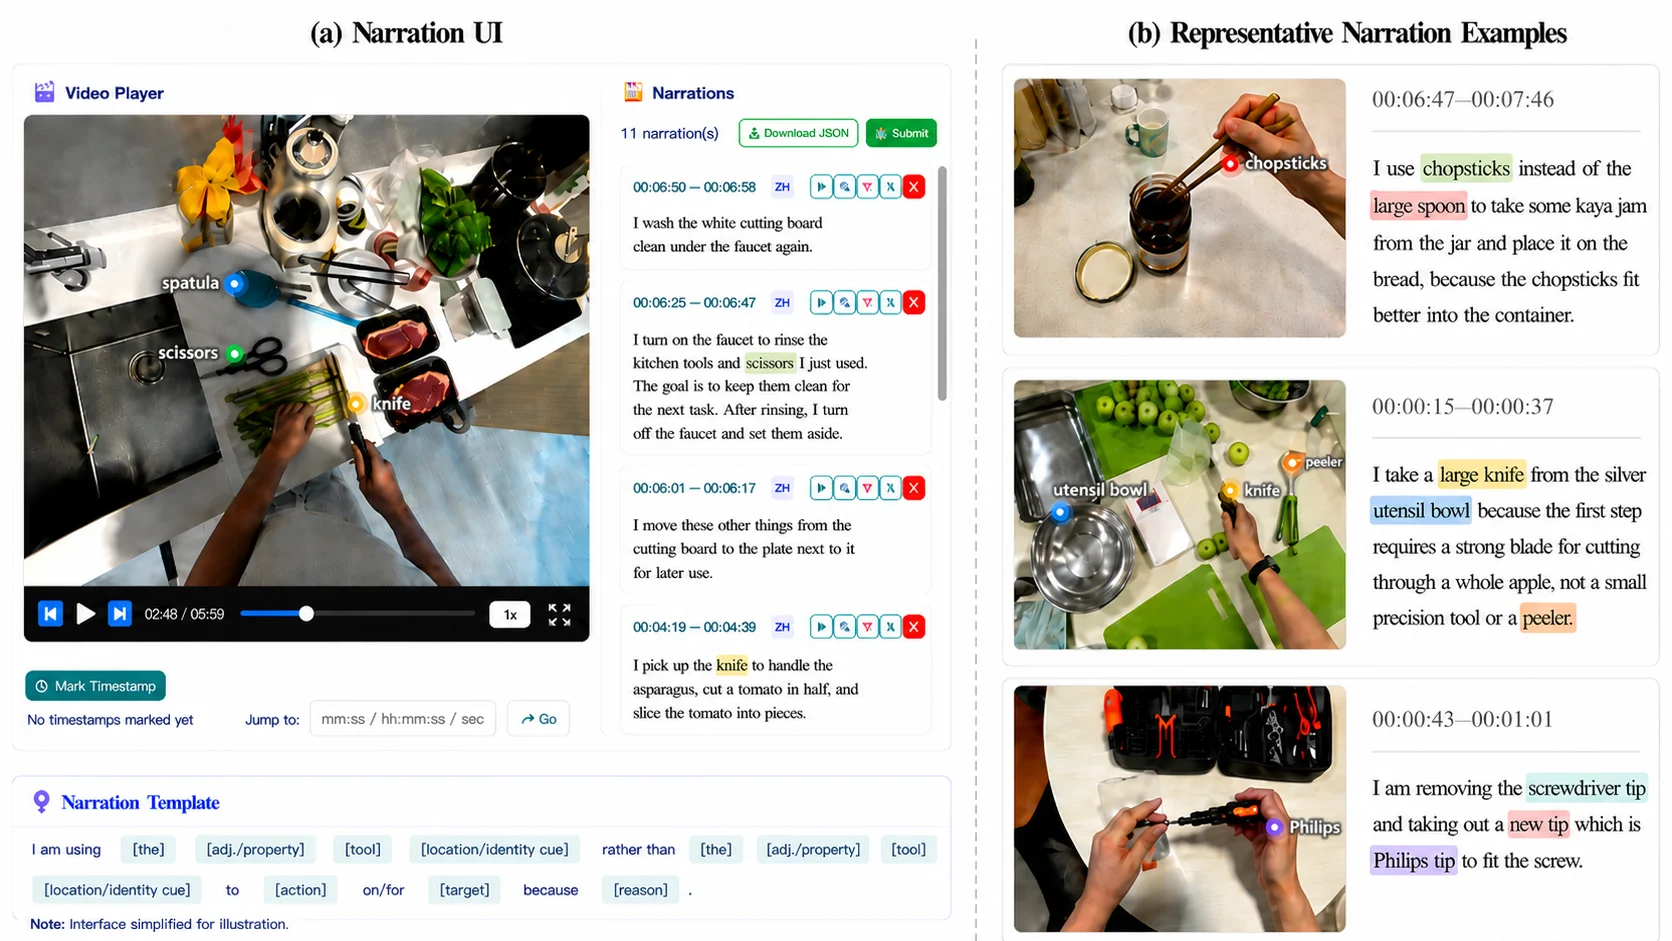
EgoTools records the decision around a tool interaction—not just a list of low-level hand motions. Tool-centric narrations connect the selected tool and its properties to the task, the intended use, and the reason it was chosen over an alternative.
That structure preserves the task-state changes needed to study affordance, causality, and procedure across long, real-world episodes.
A tool interaction becomes useful supervision when action is connected to purpose.
THE BENCHMARK
Every question asks for evidence-grounded reasoning across tool choice, perception, procedure, or spatial relations.
Why this tool, and what changes because of it?
Which object, state, property, or evidence moment?
How do steps, transitions, and outcomes connect?
How do the hand, tool, and target align in 3D?
DEMO DIFFICULTY
Pick a level. Watch the clip. Choose an answer.
THE SIGNAL
The paper reports that EgoTools supervision lifts the 8B backbone from 50.0 to 60.9, a gain of 10.9 percentage points.
12.5% chance level · 8-way multiple choice
All results reported in the current arXiv manuscript, now in one sortable ranking. Choose any track to compare every model.
Have a new run? Send the checkpoint, input protocol, predictions, and reproduction notes.
Submit to EgoTools-Bench| Rank | Model | Category | Eval. frames | Audio | |||||
|---|---|---|---|---|---|---|---|---|---|
| 01 | Human Expert | Human reference | Free-view | ✓ | 82.1 | 85.2 | 83.3 | 82.7 | 83.2 |
| 02 | Gemini-3.1-Pro | Proprietary | 1 fps | ✓ | 69.7 | 51.7 | 72.1 | 74.9 | 66.9 |
| 03 | Gemini-3-Flash | Proprietary | 1 fps | ✓ | 64.5 | 50.0 | 73.0 | 72.6 | 64.4 |
| 04 | EgoTools-8B | Ours · Fine-tuned | 64 | — | 55.4 | 59.7 | 68.1 | 44.4 | 60.9 |
| 05 | Gemini-3.1-Flash-Lite | Proprietary | 1 fps | ✓ | 58.1 | 44.5 | 59.9 | 58.7 | 55.4 |
| 06 | GLM4.1V-Thinking | Open · Reasoning | 64 | — | 46.1 | 50.0 | 57.1 | 53.3 | 50.7 |
| 07 | Qwen3-VL-8B-Instruct | Open · Instruct | 64 | — | 46.1 | 45.9 | 57.1 | 55.4 | 50.0 |
| 08 | InternVL3.5-8B-Instruct | Open · Instruct | 64 | — | 45.8 | 45.9 | 53.4 | 53.3 | 48.7 |
| 09 | InternVL3-8B-Instruct | Open · Instruct | 64 | — | 44.7 | 44.9 | 51.8 | 48.9 | 47.1 |
| 10 | Qwen2.5-Omni-7B-Instruct | Open · Instruct | 64 | ✓ | 44.7 | 45.9 | 51.8 | 46.7 | 47.1 |
| 11 | Qwen3-VL-4B-Instruct | Open · Instruct | 64 | — | 41.7 | 45.4 | 50.2 | 50.0 | 45.7 |
| 12 | Qwen3-VL-8B-Thinking | Open · Reasoning | 512 | — | 43.6 | 41.8 | 48.2 | 55.4 | 45.7 |
| 13 | MiMo-VL-7B-RL | Open · Reasoning | 64 | — | 43.1 | 45.9 | 50.6 | 39.1 | 45.3 |
| 14 | Qwen2.5-VL-7B-Instruct | Open · Instruct | 64 | — | 40.1 | 43.3 | 50.2 | 47.8 | 44.3 |
| 15 | MiMo-VL-7B-SFT | Open · Instruct | 64 | — | 41.4 | 44.9 | 49.4 | 40.2 | 44.2 |
| 16 | Qwen2-VL-7B-Instruct | Open · Instruct | 64 | — | 46.6 | 35.6 | 46.2 | 47.8 | 44.2 |
| 17 | LLaVA-Video-7B-Qwen2 | Open · Instruct | 64 | — | 38.2 | 39.7 | 43.3 | 37.0 | 39.8 |
| 18 | LLaVA-OneVision-7B | Open · Instruct | 64 | — | 37.6 | 37.1 | 42.9 | 37.0 | 38.9 |
| 19 | Qwen3-VL-4B-Thinking | Open · Reasoning | 512 | — | 37.6 | 36.6 | 36.4 | 41.3 | 37.4 |
Human Expert is shown as a free-viewing ceiling; model protocols remain visible through category, frame budget, and audio columns. Gemini models use 1 fps video.
A check means synchronized non-narration audio is provided. Narrations, dense captions, and annotation metadata are never used as evaluation inputs.
THE SYSTEM
A single traceable pipeline connects real-world collection to a model that can explain what it sees.
People choose and use tools in everyday environments, with the task unfolding over time.
Input / egocentric videoVisible actions and task progress, from short moments to longer context.
The chosen tool, its intended use, and the reason it fits the task.
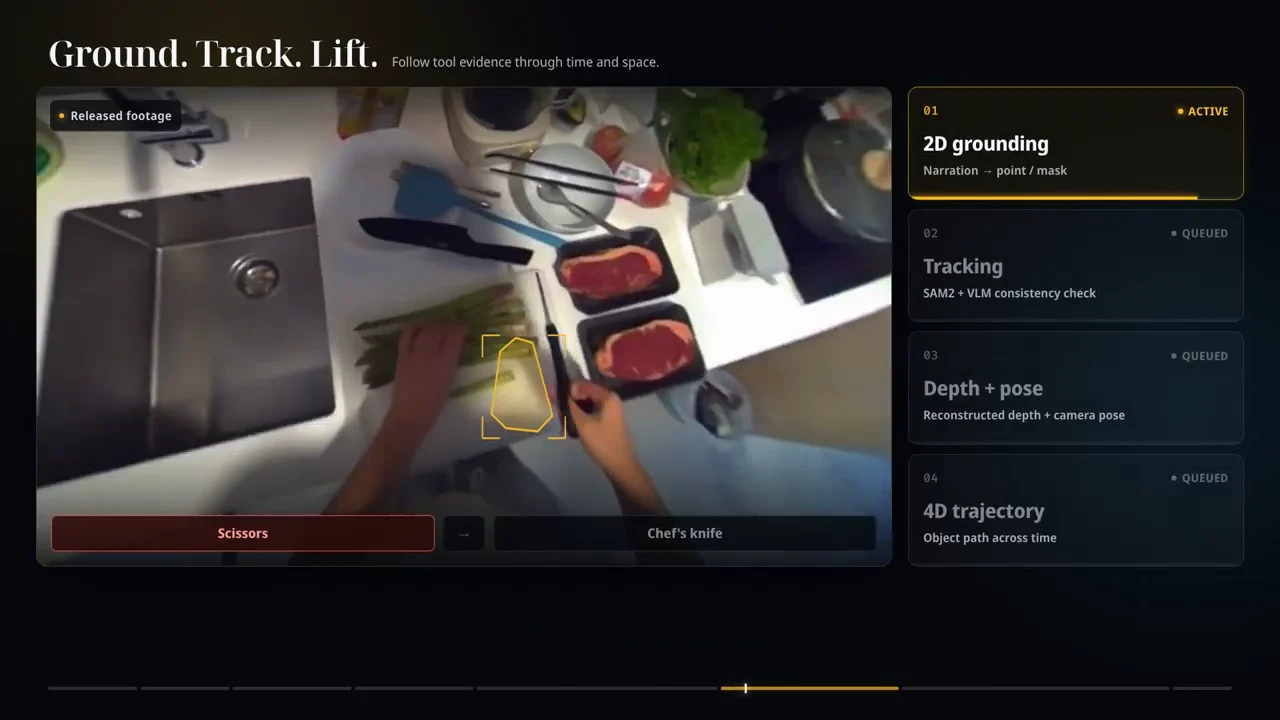
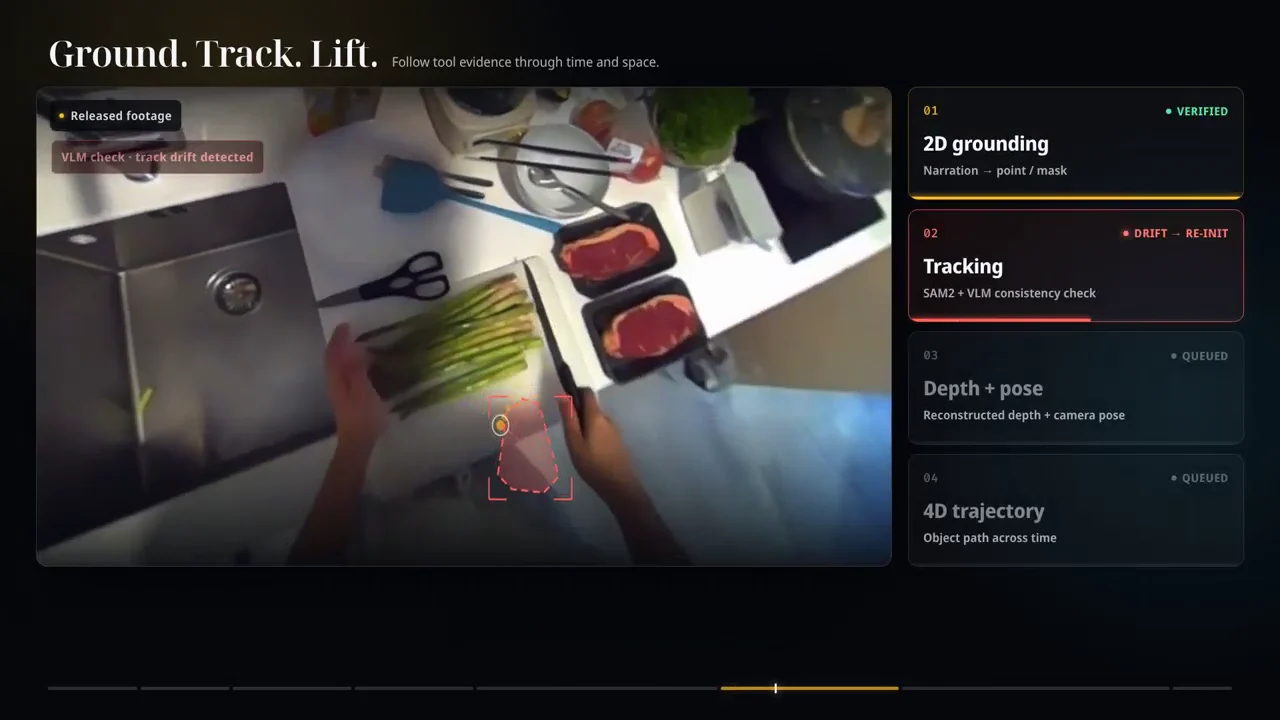
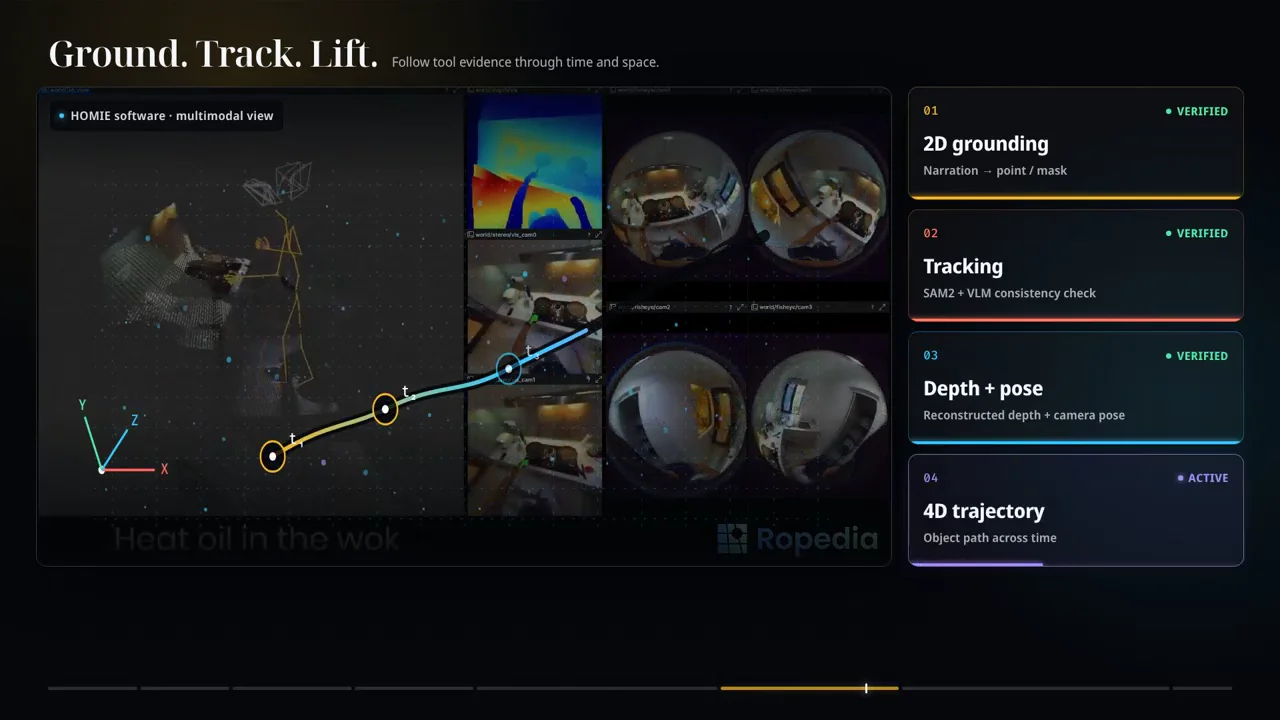
Tool + purpose + reasonTool locations in the image, tracked motion, and reconstructed trajectories.
Space + timeBenchmark source videos and their derived clips or annotations are excluded from instruction tuning.
Reserved recordings support questions about tool choice, observed states, procedure, and spatial relationships.
Training-pool videos and annotations form instruction examples for supervised video-language learning.
The reference model is evaluated on the separate benchmark pool, under the same 64-frame protocol as its backbone.
See the measured gainsRepresentative views of grounding, temporal tracking, and 3D reconstruction.
CITATION
If you use EgoTools in your research, please cite our work.
Copy the entry below or download a .bib file.
@misc{tian2026egotools,
  title = {{EgoTools}: Towards Tool-Centric Reasoning in Real-World Egocentric Videos},
  author = {Tian, Shulin and Kim, Junsu and Liu, Shuai and Li, Hao and Shen, Yujiao and
            Li, Sihan and Yang, Zhe and Kim, Yeongon and Li, Feiyu and Wu, Jialin and
            Zhang, Yichi and Wang, Wenhui and Yao, Runmao and Dong, Yuhao and Chen, Zhaoxi and
            Hong, Fangzhou and Furnari, Antonino and Yang, Jingkang and Zhu, Hongyuan and Liu, Ziwei},
  year = {2026},
  eprint = {2609.39378},
  archivePrefix = {arXiv},
  primaryClass = {cs.CV},
  doi = {10.48550/arXiv.2609.39378},
  url = {https://arxiv.org/abs/2609.39378}
}